文件
MiniMax H3 First Last Frame LoRA Trainer 变体:4
$0.01 / 步
10 API 积分 / 步
没有匹配结果。试试“video”、“FLUX”或“webhooks”。
正在加载模型…
minimax/h3/ref2va/trainer
# Run the model; wait up to 20 s for the finished result in the same call
curl -X POST "https://api.doitong.com/v1/run/minimax/h3/ref2va/trainer?wait=20" \
  -H "Authorization: Bearer $DOITONG_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "training_data_url": "https://example.com/your-file.zip"
  }'

# Still "queued" or "running"? Poll with the id from the response:
curl "https://api.doitong.com/v1/requests/REQUEST_ID?wait=20" \
  -H "Authorization: Bearer $DOITONG_API_KEY"
const API = "https://api.doitong.com/v1";
const headers = {
"Authorization": "Bearer " + process.env.DOITONG_API_KEY,
"Content-Type": "application/json",
};
// Run the model; wait up to 20 s for the finished result in the same call
let res = await fetch(API + "/run/minimax/h3/ref2va/trainer?wait=20", {
method: "POST",
headers,
body: JSON.stringify({
"training_data_url": "https://example.com/your-file.zip"
}),
});
let request = await res.json();
if (!res.ok) throw new Error(request.error.code + ": " + request.error.message);
// Not finished yet: long-poll until it is
while (request.status === "queued" || request.status === "running") {
res = await fetch(API + "/requests/" + request.id + "?wait=20", { headers });
request = await res.json();
}
if (request.status !== "succeeded") throw new Error(JSON.stringify(request.error));
console.log(request.outputs.map((o) => o.url), request.cost.credits + " API credits ($" + request.cost.usd + ")");import os
import requests
API = "https://api.doitong.com/v1"
headers = {"Authorization": "Bearer " + os.environ["DOITONG_API_KEY"]}
payload = {
"training_data_url": "https://example.com/your-file.zip",
}
# Run the model; wait up to 20 s for the finished result in the same call
r = requests.post(API + "/run/minimax/h3/ref2va/trainer", params={"wait": 20}, json=payload, headers=headers)
request = r.json()
if not r.ok:
raise RuntimeError(request["error"]["code"] + ": " + request["error"]["message"])
# Not finished yet: long-poll until it is
while request["status"] in ("queued", "running"):
request = requests.get(API + "/requests/" + request["id"], params={"wait": 20}, headers=headers).json()
if request["status"] != "succeeded":
raise RuntimeError(request["error"])
print([o["url"] for o in request["outputs"]], request["cost"]["credits"], "API credits", "$" + request["cost"]["usd"])# 1. Connect once (Claude Code; Cursor, VS Code, Claude Desktop: https://doitong.com/zh/developers/docs/mcp)
claude mcp add --transport http doitong-models https://api.doitong.com/v1/mcp \
--header "Authorization: Bearer $DOITONG_API_KEY"
# 2. Your agent calls the "run" tool with:
{
"model_id": "minimax/h3/ref2va/trainer",
"input": {
"training_data_url": "https://example.com/your-file.zip"
}
}通过 Doitong API 调用 MiniMax H3 Reference to Video LoRA Trainer 模型(minimax/h3/ref2va/trainer)。智能体文档:https://doitong.com/zh/developers/models/minimax/h3/ref2va/trainer.md
POST https://api.doitong.com/v1/run/minimax/h3/ref2va/trainer?wait=20
Authorization: Bearer $DOITONG_API_KEY
Content-Type: application/json
{
"training_data_url": "https://example.com/your-file.zip"
}
如果响应状态为 "queued" 或 "running",请轮询 GET https://api.doitong.com/v1/requests/REQUEST_ID?wait=20,直到状态变为 "succeeded";文件位于 outputs[].url。使用相同请求体 POST https://api.doitong.com/v1/quote/minimax/h3/ref2va/trainer,可在运行前返回确切价格。此请求: $30.00 30,000 API 积分 在此页面运行
你的新 API 密钥。 它仅在此时显示,并且已填入下方的代码和 API 密钥字段中。请妥善保密:切勿将其放入在浏览器中运行的代码。
Doitong 社区使用 MiniMax H3 制作的公开作品。一键复用提示词。
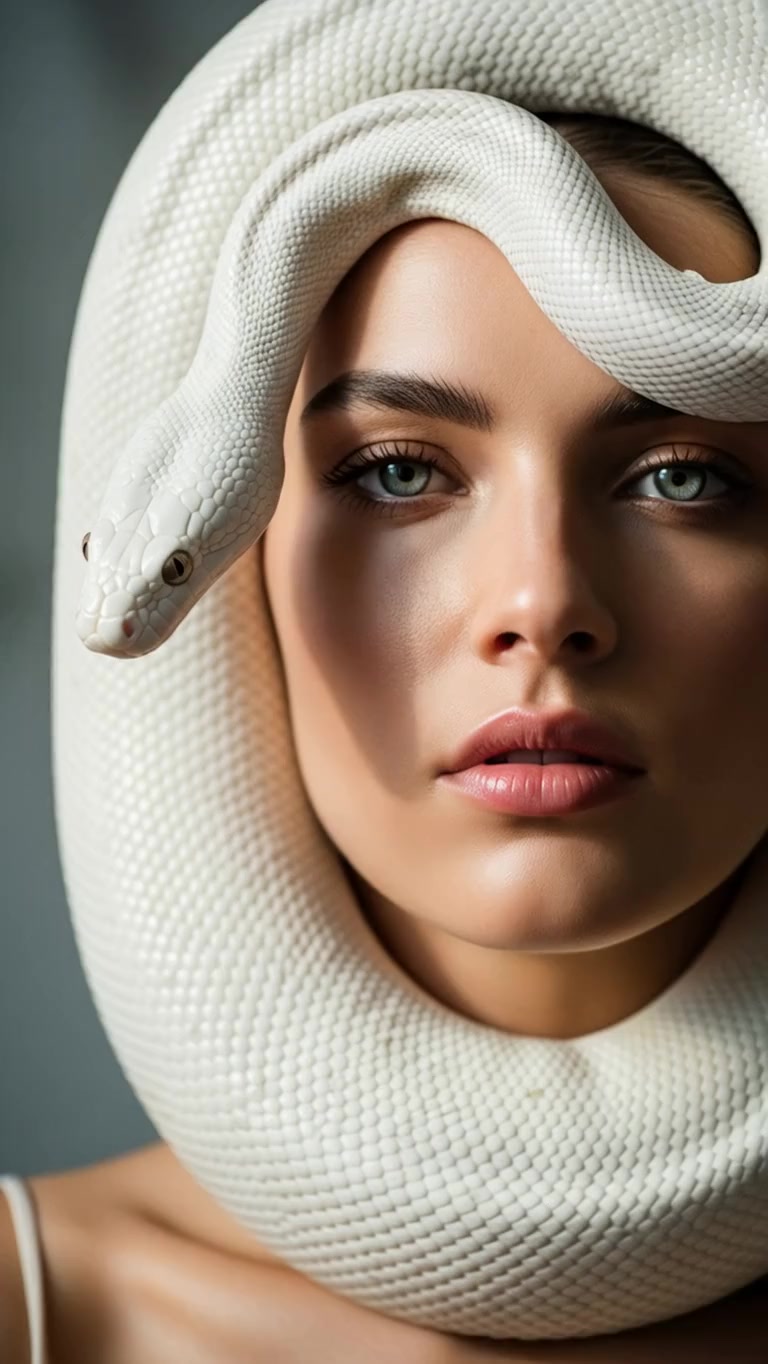 视频
Close-up shot of a striking model with piercing eyes and flawless skin, a white snake elegantly coiled around her head and neck, its scales glistening in soft, diffused light. The camera gently zooms in, emphasizing the intricate texture of the snake’s scales and the model’s striking facial...
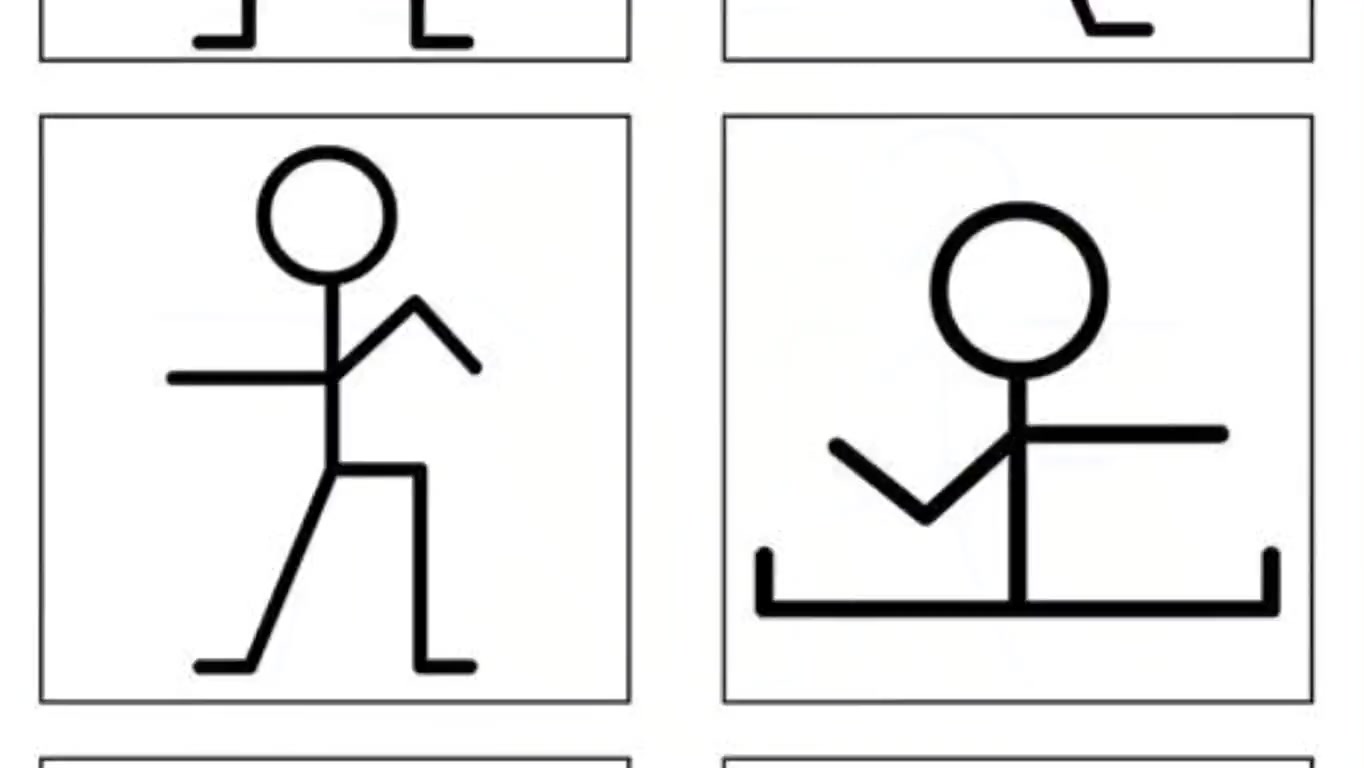 视频
Animate the stickman drawings into a smooth dance animation. The simple black stick figure performs fun rhythmic dance moves — waving its arms, bending knees, jumping lightly, spinning, and swaying side to side in time with upbeat music. Keep the white background clean and minimal. The motion...
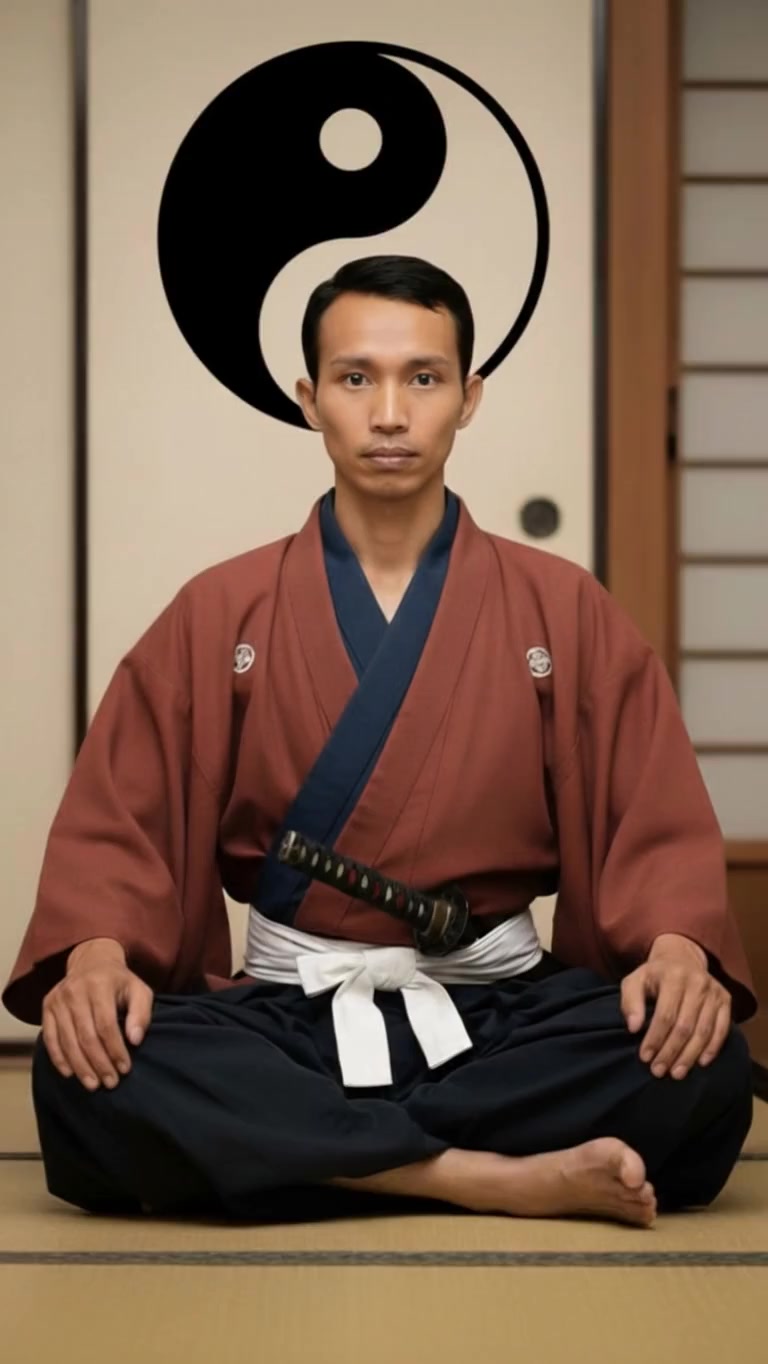 视频
A hyper-realistic, cinematic transformation sequence of the man in the uploaded image, sitting in meditation inside a traditional Japanese room. The atmosphere begins to tremble slightly as soft blue light flows around him. From the ground, thousands of magnetic nano-particles rise, shimmering...
 视频
A cinematic transformation video of the man. The scene begins with him standing naturally, then looking down at his hands as glowing holographic projections appear around his body. Mechanical parts of the Iron Man armor start assembling piece by piece with smooth animation: chest plate forming,...
 视频
An ultra-epic anime cinematic of Luffy’s greatest enemy unleashing a terrifying blind rage, rampaging uncontrollably against nature itself. His gigantic body is surrounded by a storm of black and crimson energy, crackling with lightning that scorches the ground. His roar shakes the heavens,...
 视频
A fair-skinned red-haired woman with freckles tightly embraces a majestic white tiger with faint reddish stripes. They remain close, perfectly synchronized in stillness. The woman blinks slowly, slightly tilting her head with a serious and intense expression. The tiger breathes gently — its...
 视频
The snowboarder is riding across massive, fluffy white clouds as if they were snow-covered mountains, with dramatic lighting and deep shadows adding volume and realism. The background shows a stunning blue sky with scattered soft clouds and subtle light rays. crisp cinematic quality, vivid...
 视频
[Global Parameters] Duration: 15 seconds. Aspect ratio: 16:9. Output as one continuous long-video generation with native timestamp-controlled beats as specified below. [Creatives Description] Based on the uploaded references: @image1 is the MAN — take his entire appearance 100% from this...
 视频
Extreme close-up of a smartphone on a marble kitchen table. A text notification appears on screen. A woman's elegant hand freezes above a coffee cup. Slow push-in, warm morning light, tense atmosphere, cinematic, photorealistic, vertical 9:16. A woman speaks softly in Russian, whispering in a...
Art style: warm European aesthetic, golden hour light, soft bokeh, intimate close-ups, film grain, muted warm tones. Мужчина нажимает кнопку звонка, держа цветок. Дверь открывается, и перед ним предстает удивленная девушка. Оба замирают на месте в полном оцепенении от взаимного узнавания, не...
Art style: 3D Pixar. Каспер решительно парит навстречу Теневому Стражу, свет вокруг них усиливается, Лена наблюдает сзади. Камера остаётся неподвижной. ━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━ FINAL STYLE ENFORCEMENT (this is the authoritative rendering directive — it overrides any style wording...
Art style: Classic Fairytale. RAPID MULTI-CUT SEQUENCE, ~5 hard cuts. Clinical top-down white light, palette stark white / deep black / pale skin. (0-1s) EXTREME CLOSE-UP: @Detective Alexander Vance's black-nitrile-gloved fingers press into the victim's pale neck. No pulse. Held, dead still....
Camera: orbit. Art style: DreamWorks-inspired. Low-angle cinematic shot of the gray wolf raising its head and howling melodically. Camera catches the golden late afternoon light catching the wolf's fur and the awe on Talisa and Elky's faces. SPOKEN LINE — AUTHORITATIVE, overrides any line quoted...
Camera: dolly out. Art style: DreamWorks-inspired. Camera slowly cranes upward and pulls backward into a wide panoramic sunset shot of the cozy cabin at the forest edge as Talisa and Elky reach the front door, with Elky cheering joyfully. SPOKEN LINE — AUTHORITATIVE, overrides any line quoted...
Art style: Ghibli-style anime illustration. She gently dries the rabbit's fur. The fire glows and sparks. The camera captures the cozy, safe atmosphere. ━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━ FINAL STYLE ENFORCEMENT (this is the authoritative rendering directive — it overrides any style wording...
Art style: Photorealistic Cinematic Adventure Naturalism. Continue directly from the source image. Preserve Mara and Rhyss exactly as shown in the source image. Do not change their appearance, anatomy, clothing, proportions or scale. Rhyss and Mara move together upward and forward toward the...
控件根据模型架构生成。更改控件时,代码和价格会同步更新。
/run/minimax/h3/ref2va/trainer?wait=20
报价 → $30.00
# Run the model; wait up to 20 s for the finished result in the same call
curl -X POST "https://api.doitong.com/v1/run/minimax/h3/ref2va/trainer?wait=20" \
  -H "Authorization: Bearer $DOITONG_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "training_data_url": "https://example.com/your-file.zip"
  }'

# Still "queued" or "running"? Poll with the id from the response:
curl "https://api.doitong.com/v1/requests/REQUEST_ID?wait=20" \
  -H "Authorization: Bearer $DOITONG_API_KEY"
const API = "https://api.doitong.com/v1";
const headers = {
"Authorization": "Bearer " + process.env.DOITONG_API_KEY,
"Content-Type": "application/json",
};
// Run the model; wait up to 20 s for the finished result in the same call
let res = await fetch(API + "/run/minimax/h3/ref2va/trainer?wait=20", {
method: "POST",
headers,
body: JSON.stringify({
"training_data_url": "https://example.com/your-file.zip"
}),
});
let request = await res.json();
if (!res.ok) throw new Error(request.error.code + ": " + request.error.message);
// Not finished yet: long-poll until it is
while (request.status === "queued" || request.status === "running") {
res = await fetch(API + "/requests/" + request.id + "?wait=20", { headers });
request = await res.json();
}
if (request.status !== "succeeded") throw new Error(JSON.stringify(request.error));
console.log(request.outputs.map((o) => o.url), request.cost.credits + " API credits ($" + request.cost.usd + ")");import os
import requests
API = "https://api.doitong.com/v1"
headers = {"Authorization": "Bearer " + os.environ["DOITONG_API_KEY"]}
payload = {
"training_data_url": "https://example.com/your-file.zip",
}
# Run the model; wait up to 20 s for the finished result in the same call
r = requests.post(API + "/run/minimax/h3/ref2va/trainer", params={"wait": 20}, json=payload, headers=headers)
request = r.json()
if not r.ok:
raise RuntimeError(request["error"]["code"] + ": " + request["error"]["message"])
# Not finished yet: long-poll until it is
while request["status"] in ("queued", "running"):
request = requests.get(API + "/requests/" + request["id"], params={"wait": 20}, headers=headers).json()
if request["status"] != "succeeded":
raise RuntimeError(request["error"])
print([o["url"] for o in request["outputs"]], request["cost"]["credits"], "API credits", "$" + request["cost"]["usd"]){
"jsonrpc": "2.0",
"id": 1,
"method": "tools/call",
"params": {
"name": "run",
"arguments": {
"model_id": "minimax/h3/ref2va/trainer",
"input": {
"training_data_url": "https://example.com/your-file.zip"
},
"wait_seconds": 20
}
}
}根据主体视频片段的 zip 文件训练 LoRA,使参考输入能够引导视频生成。`reference_conditioning_p` 设置训练期间使用参考内容的频率,`resume_from_lora_url` 从之前训练的 LoRA 继续训练。还可配置:`rank`、`number_of_steps`、`number_of_frames`、`frame_rate` 和 `aspect_ratio`。返回权重和配置文件。
training_data_url必填
rank可选
number_of_steps可选
learning_rate可选
number_of_frames可选
frame_rate可选
resolution可选
aspect_ratio可选
trigger_phrase可选
reference_conditioning_p可选
resume_from_lora_url可选
auto_scale_input可选
split_input_into_scenes可选
split_input_duration_threshold可选
debug_dataset可选
strict_dataset可选
{
  "id": "req_8k2m4q7x1z9c3v5b6n0p2r4t",
  "object": "request",
  "model": "minimax/h3/ref2va/trainer",
  "status": "succeeded",
  "created_at": "2026-10-20T12:00:00Z",
  "started_at": "2026-10-20T12:00:02Z",
  "completed_at": "2026-10-20T12:00:09Z",
  "queue_position": null,
  "cost": {
    "credits": 30000,
    "usd": "30.00",
    "charged": 30000,
    "refunded": 0
  },
  "input": {
    "training_data_url": "https://example.com/your-file.zip"
  },
  "output": {
    "lora_file": {
      "url": "https://content.doitong.com/dev-api/2026/10/20/req_8k2m4q7x1z9c3v5b6n0p2r4t/0-output.jpeg",
      "content_type": "image/jpeg",
      "file_name": "0-output.jpeg",
      "file_size": 1843200
    },
    "config_file": {
      "url": "https://content.doitong.com/dev-api/2026/10/20/req_8k2m4q7x1z9c3v5b6n0p2r4t/0-output.jpeg",
      "content_type": "image/jpeg",
      "file_name": "0-output.jpeg",
      "file_size": 1843200
    },
    "debug_dataset": {
      "url": "https://content.doitong.com/dev-api/2026/10/20/req_8k2m4q7x1z9c3v5b6n0p2r4t/0-output.jpeg",
      "content_type": "image/jpeg",
      "file_name": "0-output.jpeg",
      "file_size": 1843200
    }
  },
  "outputs": [
    {
      "type": "file",
      "url": "https://content.doitong.com/dev-api/2026/10/20/req_8k2m4q7x1z9c3v5b6n0p2r4t/0-output.jpeg",
      "content_type": "image/jpeg",
      "file_size": 1843200,
      "stored": true
    }
  ],
  "error": null,
  "metrics": {
    "inference_seconds": 6.8
  },
  "urls": {
    "self": "https://api.doitong.com/v1/requests/req_8k2m4q7x1z9c3v5b6n0p2r4t",
    "cancel": "https://api.doitong.com/v1/requests/req_8k2m4q7x1z9c3v5b6n0p2r4t/cancel"
  }
}对于 AI 代理:此页面的 Markdown 版本位于 https://doitong.com/zh/developers/models/minimax/h3/ref2va/trainer.md. 所有模型和指南: https://doitong.com/developers/llms.txt